01 · CHALLENGE
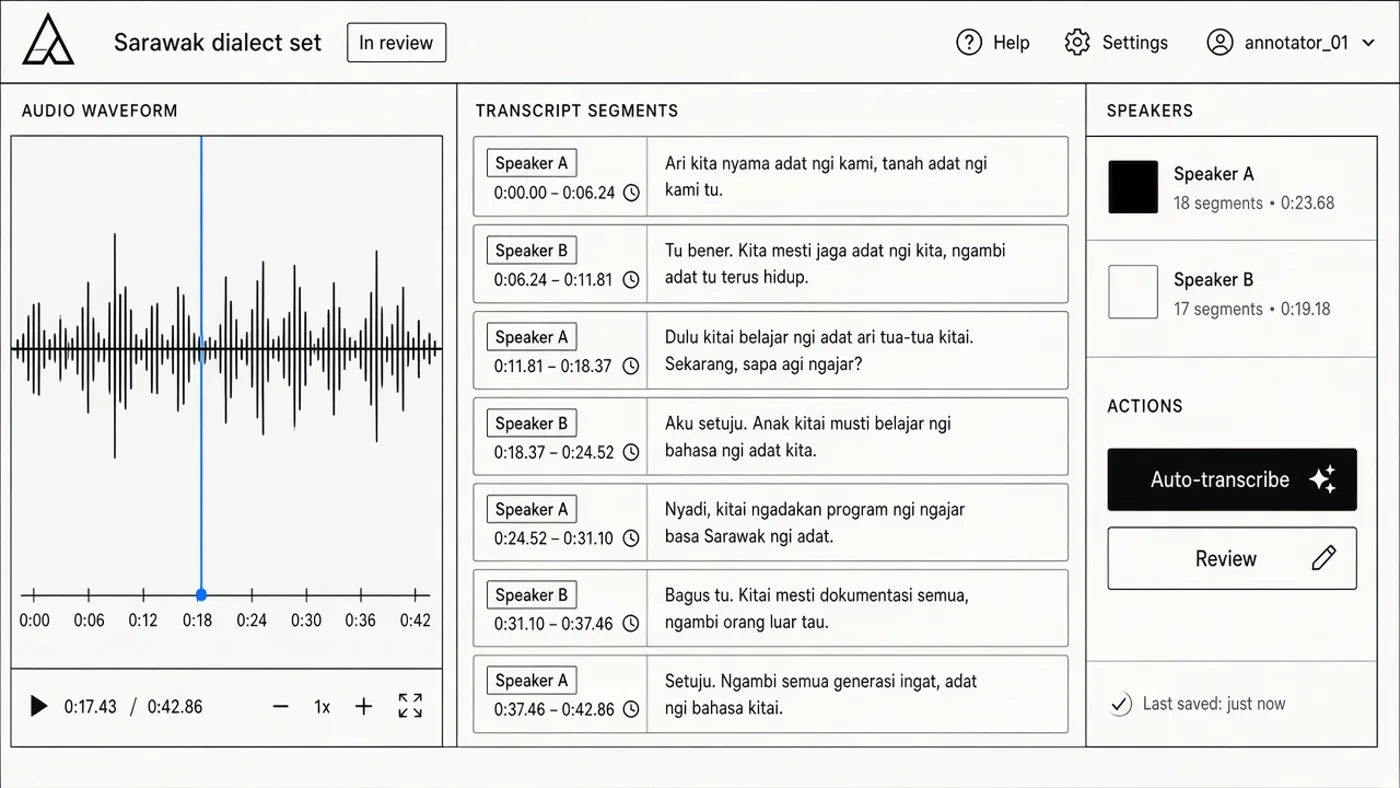
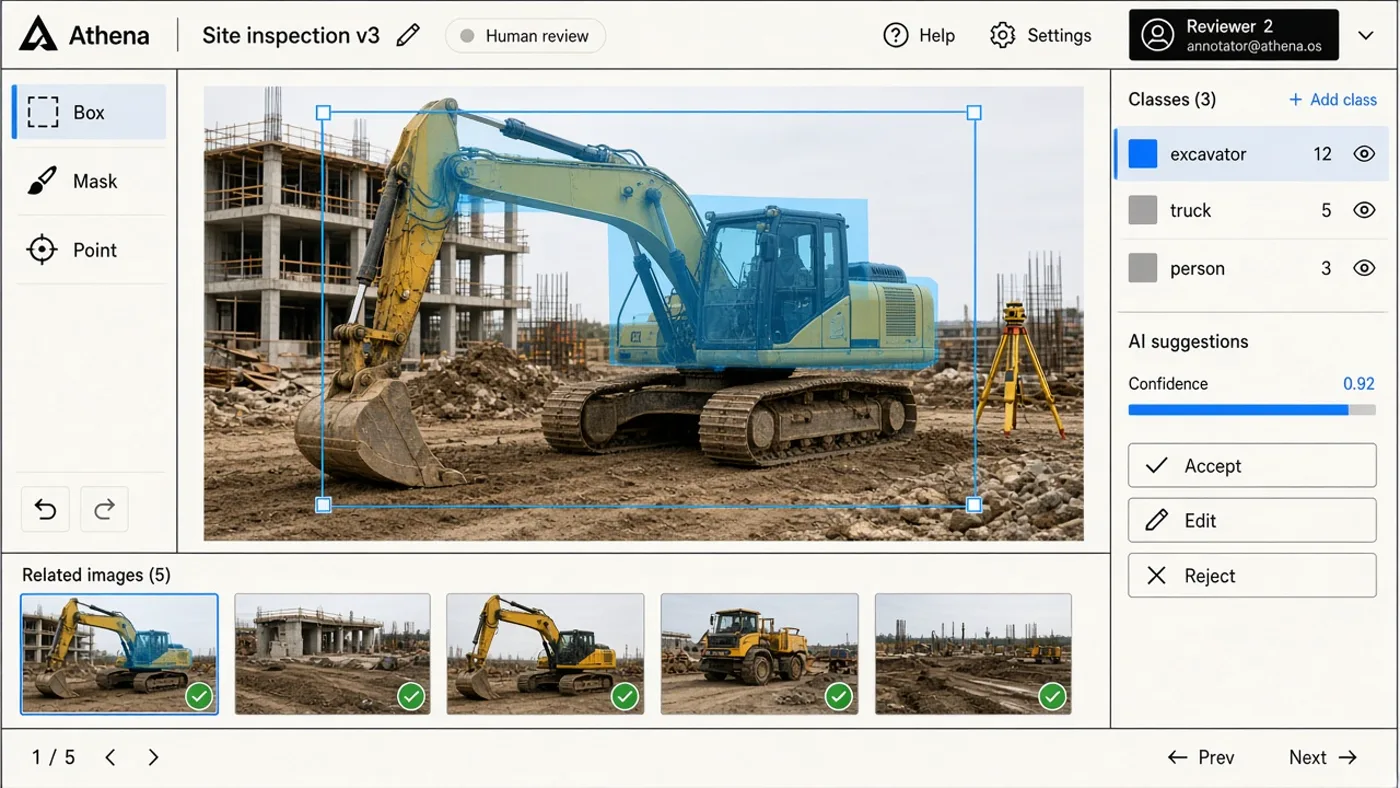
AI projects need useful, well-organized labels before models can produce useful results—especially for local dialects and carefully drawn image annotations.
FIELD GUIDE · BUILD
Open-source data labeling for dialect audio and images, with AI assistance and human review as the quality gate.
ATHENA / INSPEC-THER · STATUS BELOW
01 · CHALLENGE
AI projects need useful, well-organized labels before models can produce useful results—especially for local dialects and carefully drawn image annotations.
02 · ROLE
Founder / builder — product direction, labeling workflows, and public technical writing.
03 · DESIGN DECISIONS
04 · SCREENSHOTS / MEDIA
CURRENT STATE
Public product surface and technical field notes are live. Treat the product as a working prototype under active development—not a finished commercial claim.
WHAT I LEARNED
BUILD RECEIPTS
MORE BUILDS